ChatGPT for business is first and foremost a decision about data and responsibility. The tool drafts texts, summarizes long documents, and answers questions in seconds. For this to become an asset, three things are required: the right contract, knowledge of the system's weaknesses, and binding rules within the team.
The pent-up demand is measurable. 26 percent companies in Germany used artificial intelligence technologies in 2025, according to data collected by the Federal Statistical Office. For companies with 250 or more employees, it was 57 percent, and for companies with 10 to 49 employees, 23 percent. How this distribution is developing, we have summarized in AI in German companies compiled.
Where ChatGPT saves time in everyday work
The greatest benefit lies in tasks with a lot of text and little decision-making power. Summarizing minutes, standardizing proposal texts, drafting an English customer email, extracting a short version from ten pages of documentation: these activities eat up hours and rarely require specialized knowledge that only exists in a specific person's head. Anyone who starts there will notice the difference after a few days. A ChatGPT Within the team, this saves time, especially on tasks that no one previously wanted to take on.
It gets more difficult as soon as technical depth comes into play. A Large Language Model (LLM) does not know your price list, your delivery times, or a customer's history. It fills these gaps with plausibly sounding formulations. Therefore, its use works best where a human reviews the result anyway before it leaves the company.
Data protection starts with the choice of plan
You set the most important course when signing the contract. In OpenAI's business offers, inputs and outputs are not used by default to train the models. For the programming interface, the provider maintains in its developer documentation It explicitly states that the data you send will only improve the models if you actively consent to it. In the free plans, this setting is configured differently and must be changed manually.
Then there's the contractual aspect. Anyone who processes personal data needs a Data Processing Agreement with the provider, and this is included in the scope of services covered by the business plans. By default, logs are generated for fraud detection and are retained for up to 30 days; for authorized customers, there are options to limit these logs or to refrain from storing content altogether. Before implementation, determine which of these components you need, record the results in your processing inventory, and specify who will manage access.
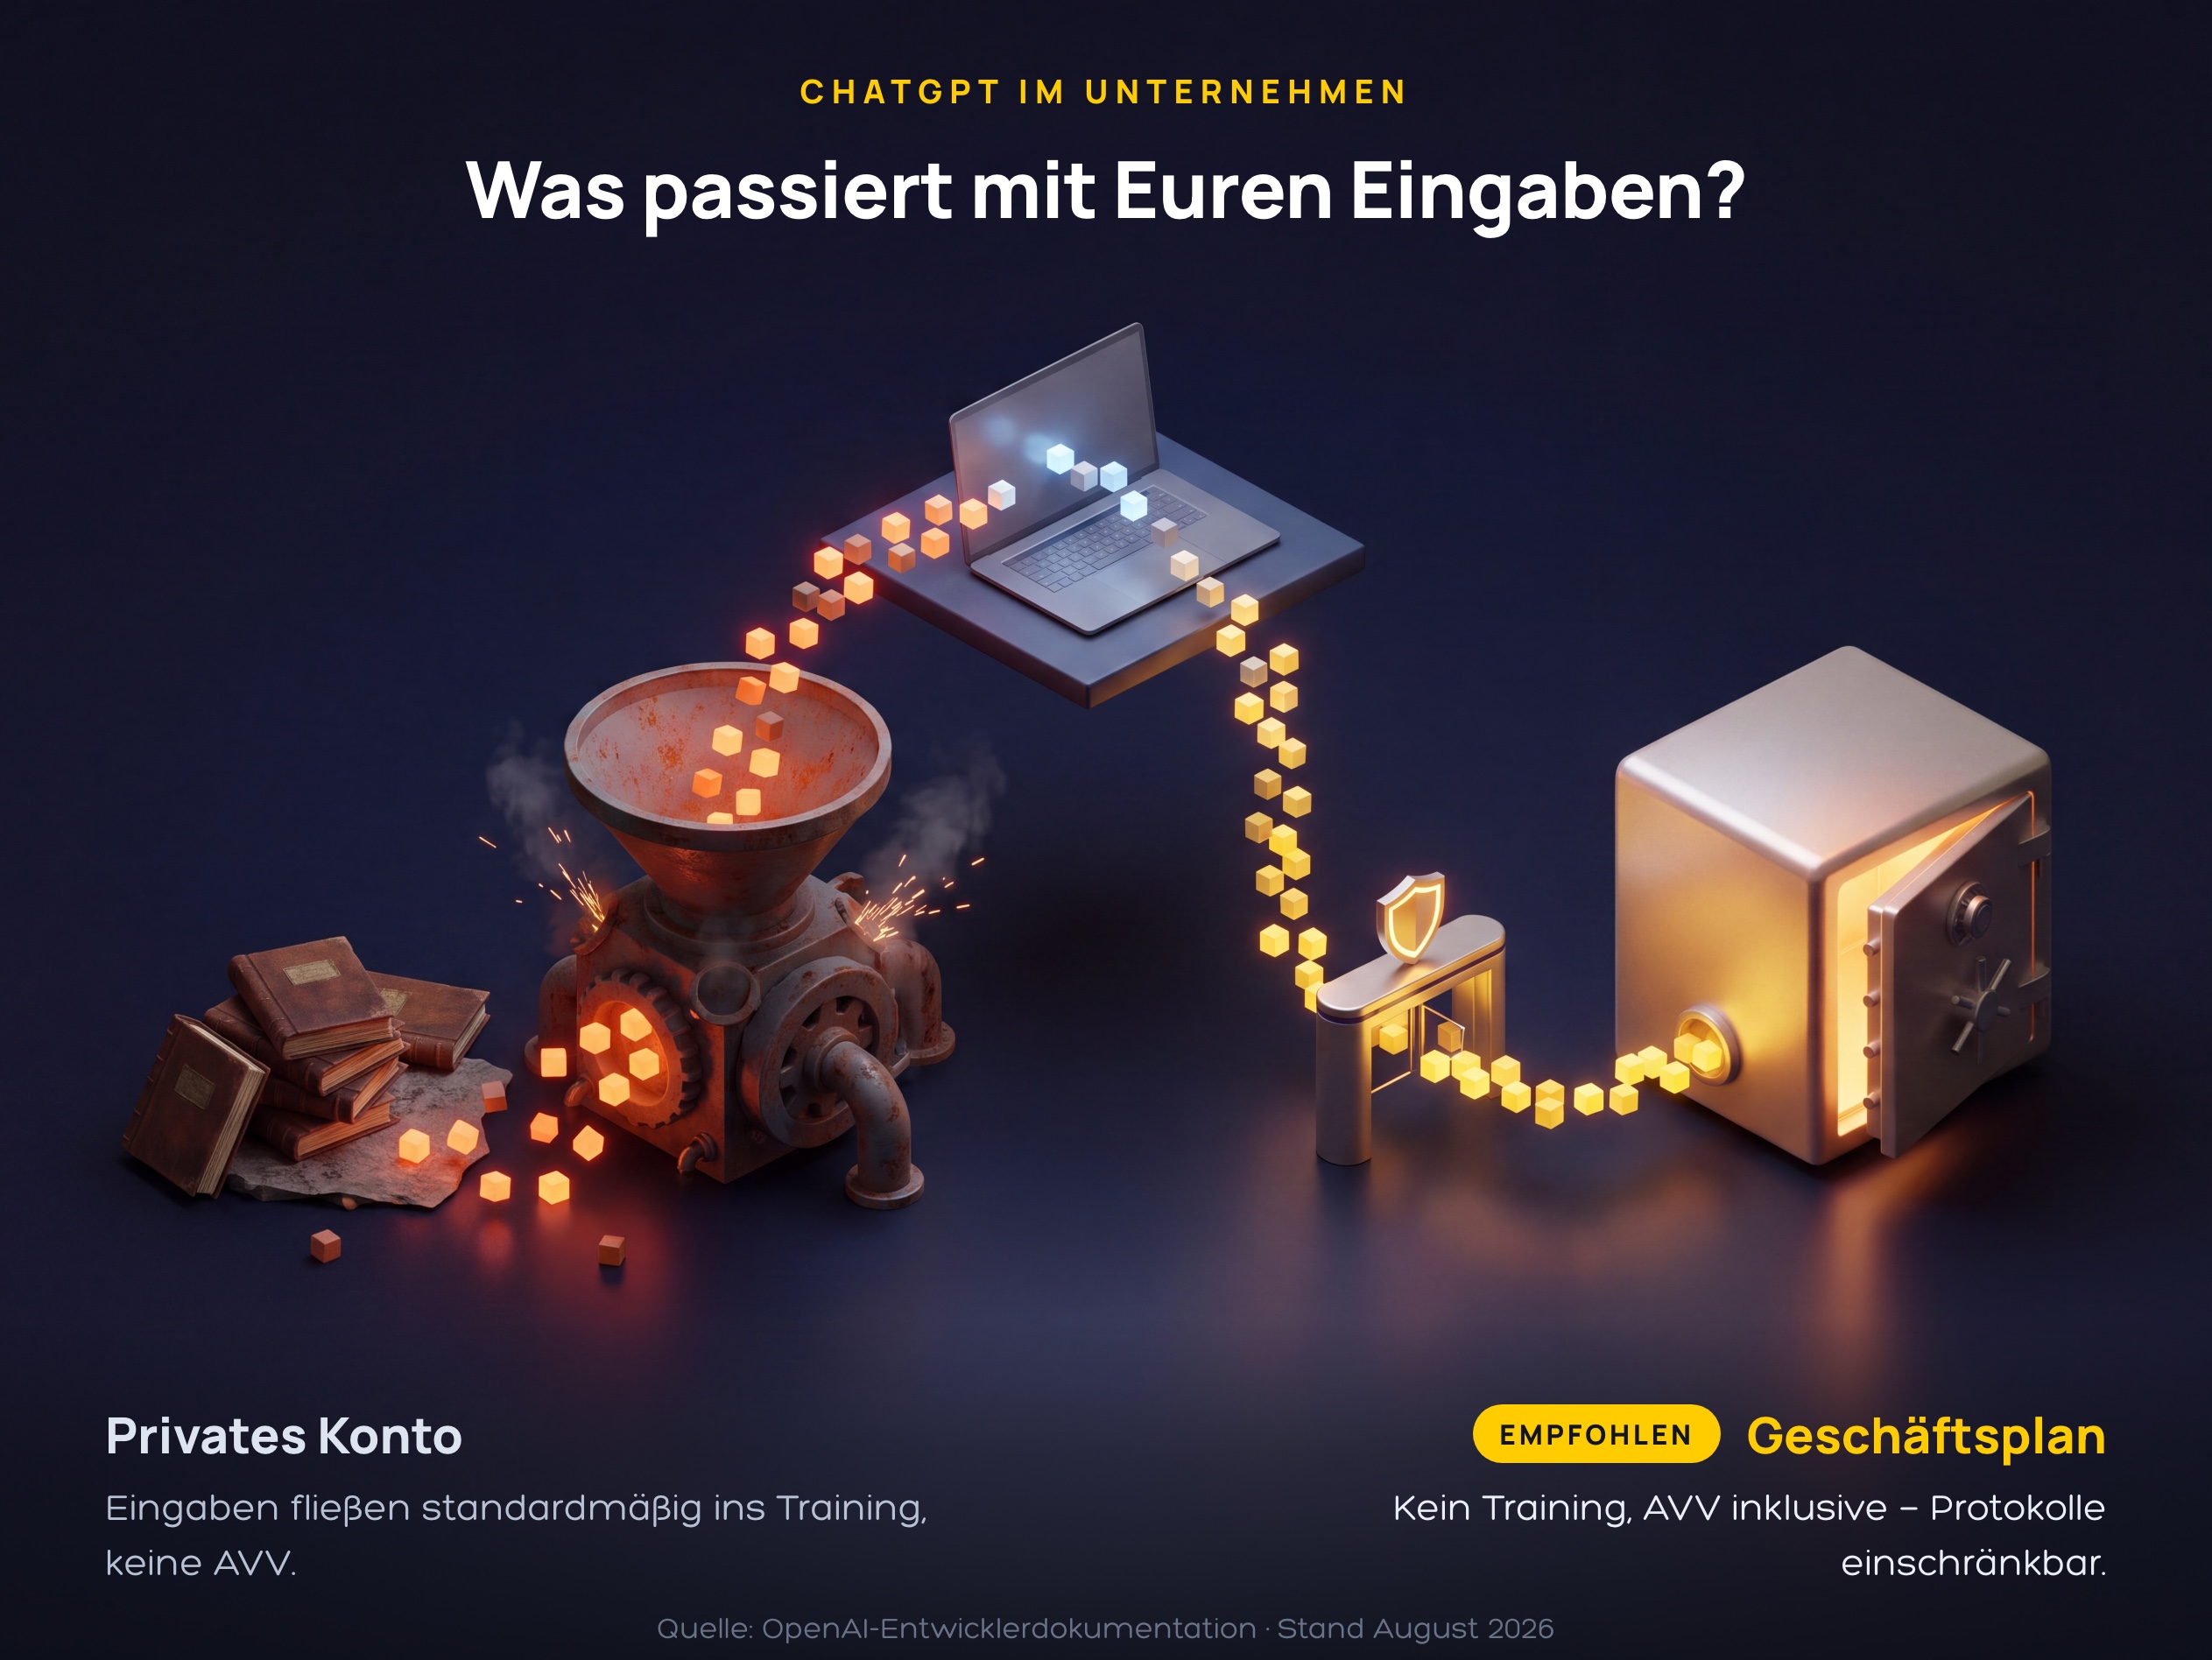
The difference lies in the path of your inputs: in the personal account, they flow into the training of the models by default, and a data processing agreement is missing. In the business plan, they pass through a contractual barrier—no training, the DPA is part of the scope of services, and the logs for abuse detection can be restricted.
Where ChatGPT hits its limits for businesses
The best-known weakness is Hallucinations. The The Fraunhofer Institute for Experimental Software Engineering describes them as content that appears realistic, but deviates from the given sources or is factually incorrect. The causes lie in the training data, the training procedure, and the way answers are generated word by word. Even with a thin factual basis, a model delivers a fluent sentence and rarely reports its own uncertainty on its own initiative. These points need to be put on the table before the rollout:
- Fabricated details: Numbers, names, legal provisions, and citations may appear accurate but are sometimes incorrect. Any information released to the public must be cross-checked against the original source.
- Missing operational context: Without attached documents, your products, prices, and internal processes will remain invisible to the system. Responses to these topics will then be based on general templates from the training.
- Current state of knowledge: Statements about current events are only reliable if the tool has demonstrably conducted research online. Without such research, the model falls back on older data.
- Confidentiality: Content entered into a private account is completely beyond your control. For customer data, contracts, and personnel records, this is a dealbreaker.
- Uniform tone: Without specifications for style and choice of words, all results look similar, which is noticeable in customer communication. A brief style guide per type of text solves this reliably.
How to Introduce ChatGPT to Your Team
Rolling out a system without rules leads to chaos: Some colleagues use personal accounts, others don’t use any at all, and no one knows where the data has ended up. A limited rollout with two or three use cases, a business plan for all stakeholders, and a brief written guideline leads more quickly to reliable results. The EU AI Act also obligates providers and operators since the February 2, 2025 for this, for a sufficient level of AI literacy to take care of our own staff. These steps have proven effective:
- Define use cases: Select two to three text-heavy tasks and start there with measurable goals. Anyone who opens everything at once cannot evaluate anything in the end.
- Centralized assignment of access rights: A business plan for the entire team ensures that business content remains in an account with a data processing agreement. Administration belongs in a designated responsibility.
- Create a tab list: Keep in mind what should never be entered, such as health data, application documents, third-party contracts, or access credentials. One page is enough, everyone just needs to know it.
- Anchor the four-eyes principle: Everything that goes to customers, partners, or authorities is proofread and approved by a human. The responsibility for the content remains with the person who sends it.
- Schedule training: Half a day too Prompt Engineering, data protection, and typical failure patterns covers the beginning and simultaneously fulfills the competence obligation. It documents participants and content for later records.
- After making adjustments after eight weeks: Gathering experience, adapting the guideline, and releasing further use cases. What has not proven successful will be eliminated.
Where the entry point with internal resources fails, an external one helps AI consulting thereby nailing down use cases and framework conditions within a few weeks.
FAQs on ChatGPT for Businesses
Can ChatGPT be used by companies in compliance with the GDPR?
Yes, conditionally. You need a business plan with a data processing agreement, you must document the processing in your records, and you may only enter the data that is necessary for the respective task. A private account for work-related content does not meet these requirements.
Are our inputs used to train the models?
By default, not in the business offers. For the API, OpenAI states that submitted data only improves the models if you actively opt in. In the free access tiers, the default setting is different and must be changed manually in the data controls.
Which tasks are suitable for getting started?
Tasks with a lot of text and low risk: summaries, translations, first drafts for standard correspondence, and standardizing existing texts. Tasks with legal or financial significance belong in a later phase, once review paths and responsibilities are established. As a rule of thumb, anything that undergoes a second reading anyway is suitable.
How do we prevent false information in customer texts?
Through a rigorous verification process before shipping. Every number, every name, and every citation is checked, and no text leaves the house without human approval. Where operational knowledge is concerned, you include the relevant documents directly in the request instead of relying on the model's general knowledge.
Do we need to train our employees?
Yes. Since February 2, 2025, the EU AI Act has required providers and deployers to ensure a sufficient level of AI literacy among the persons operating these systems on their behalf. A brief, documented training session serves this purpose and at the same time reduces the error rate in everyday operations.